AI / News
Qwen3.8-Flash-Next: open weights do not mean a lightweight PC model
The new Qwen opens its weights and previews a future architecture. Active parameters alone do not describe the hardware needed to run a model.
Redação AnderZilla ·
Verified: · Announcement or event date:
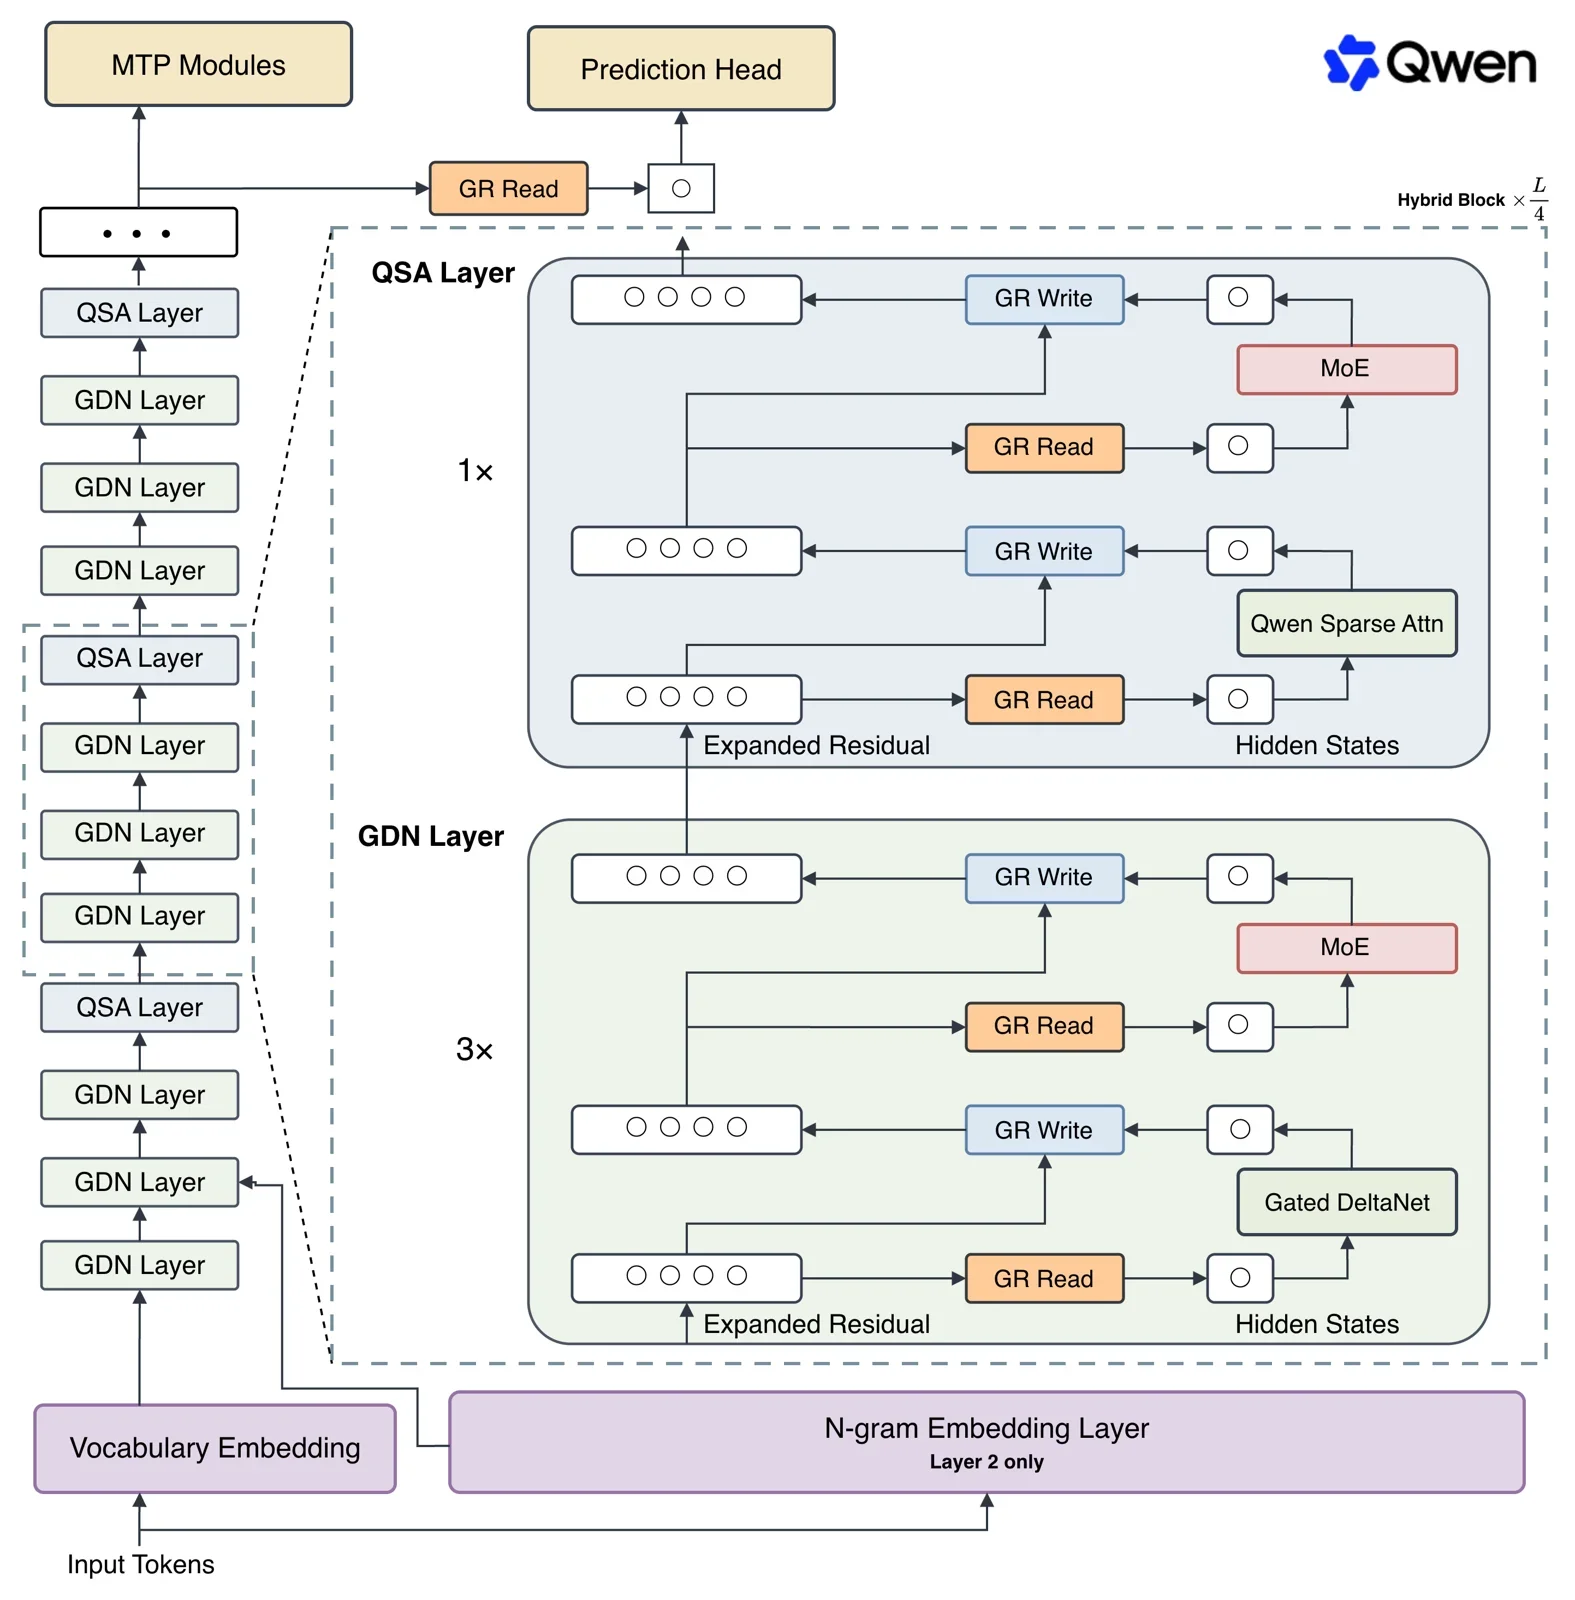
The Qwen team released Qwen3.8-Flash-Next on August 26. The multimodal model uses a mixture-of-experts architecture with six billion active parameters per token and a much larger total foundation. Its weights were made available to the community.
That smaller number is eye-catching if you want to run AI on a gaming PC. Active parameters describe part of the computation, however, not a promise about total memory requirements. Before downloading, consider the weight format, runtime and intended context size.
Our evaluation approach starts with the actual goal: local conversation, image analysis or a tool integration? Then consult documentation for that specific configuration and check storage, system memory and VRAM. The word Flash alone cannot establish that an ordinary graphics card will run the model.
Keep the distributed model separate from the hosted service as well: their tools and configurations can differ. This is an interesting release for people following AI engineering in China and developers exploring alternatives. Treat it as a research opportunity, without inventing compatibility or performance we have not measured on real hardware.
Sources: Qwen Team. Checked September 10, 2026. Document-based reporting; no hands-on test.
Sources and reporting context (1)
Original source: Qwen Team — Flash-Next ↗
Back to discoveries →